

The AI engineering platform for teams shipping reliable AI agents and LLM applications. Also home to @ArizePhoenix.
San Francisco, CA
- Tweets 1,914
- Following 164
- Followers 5,149
- Likes 723


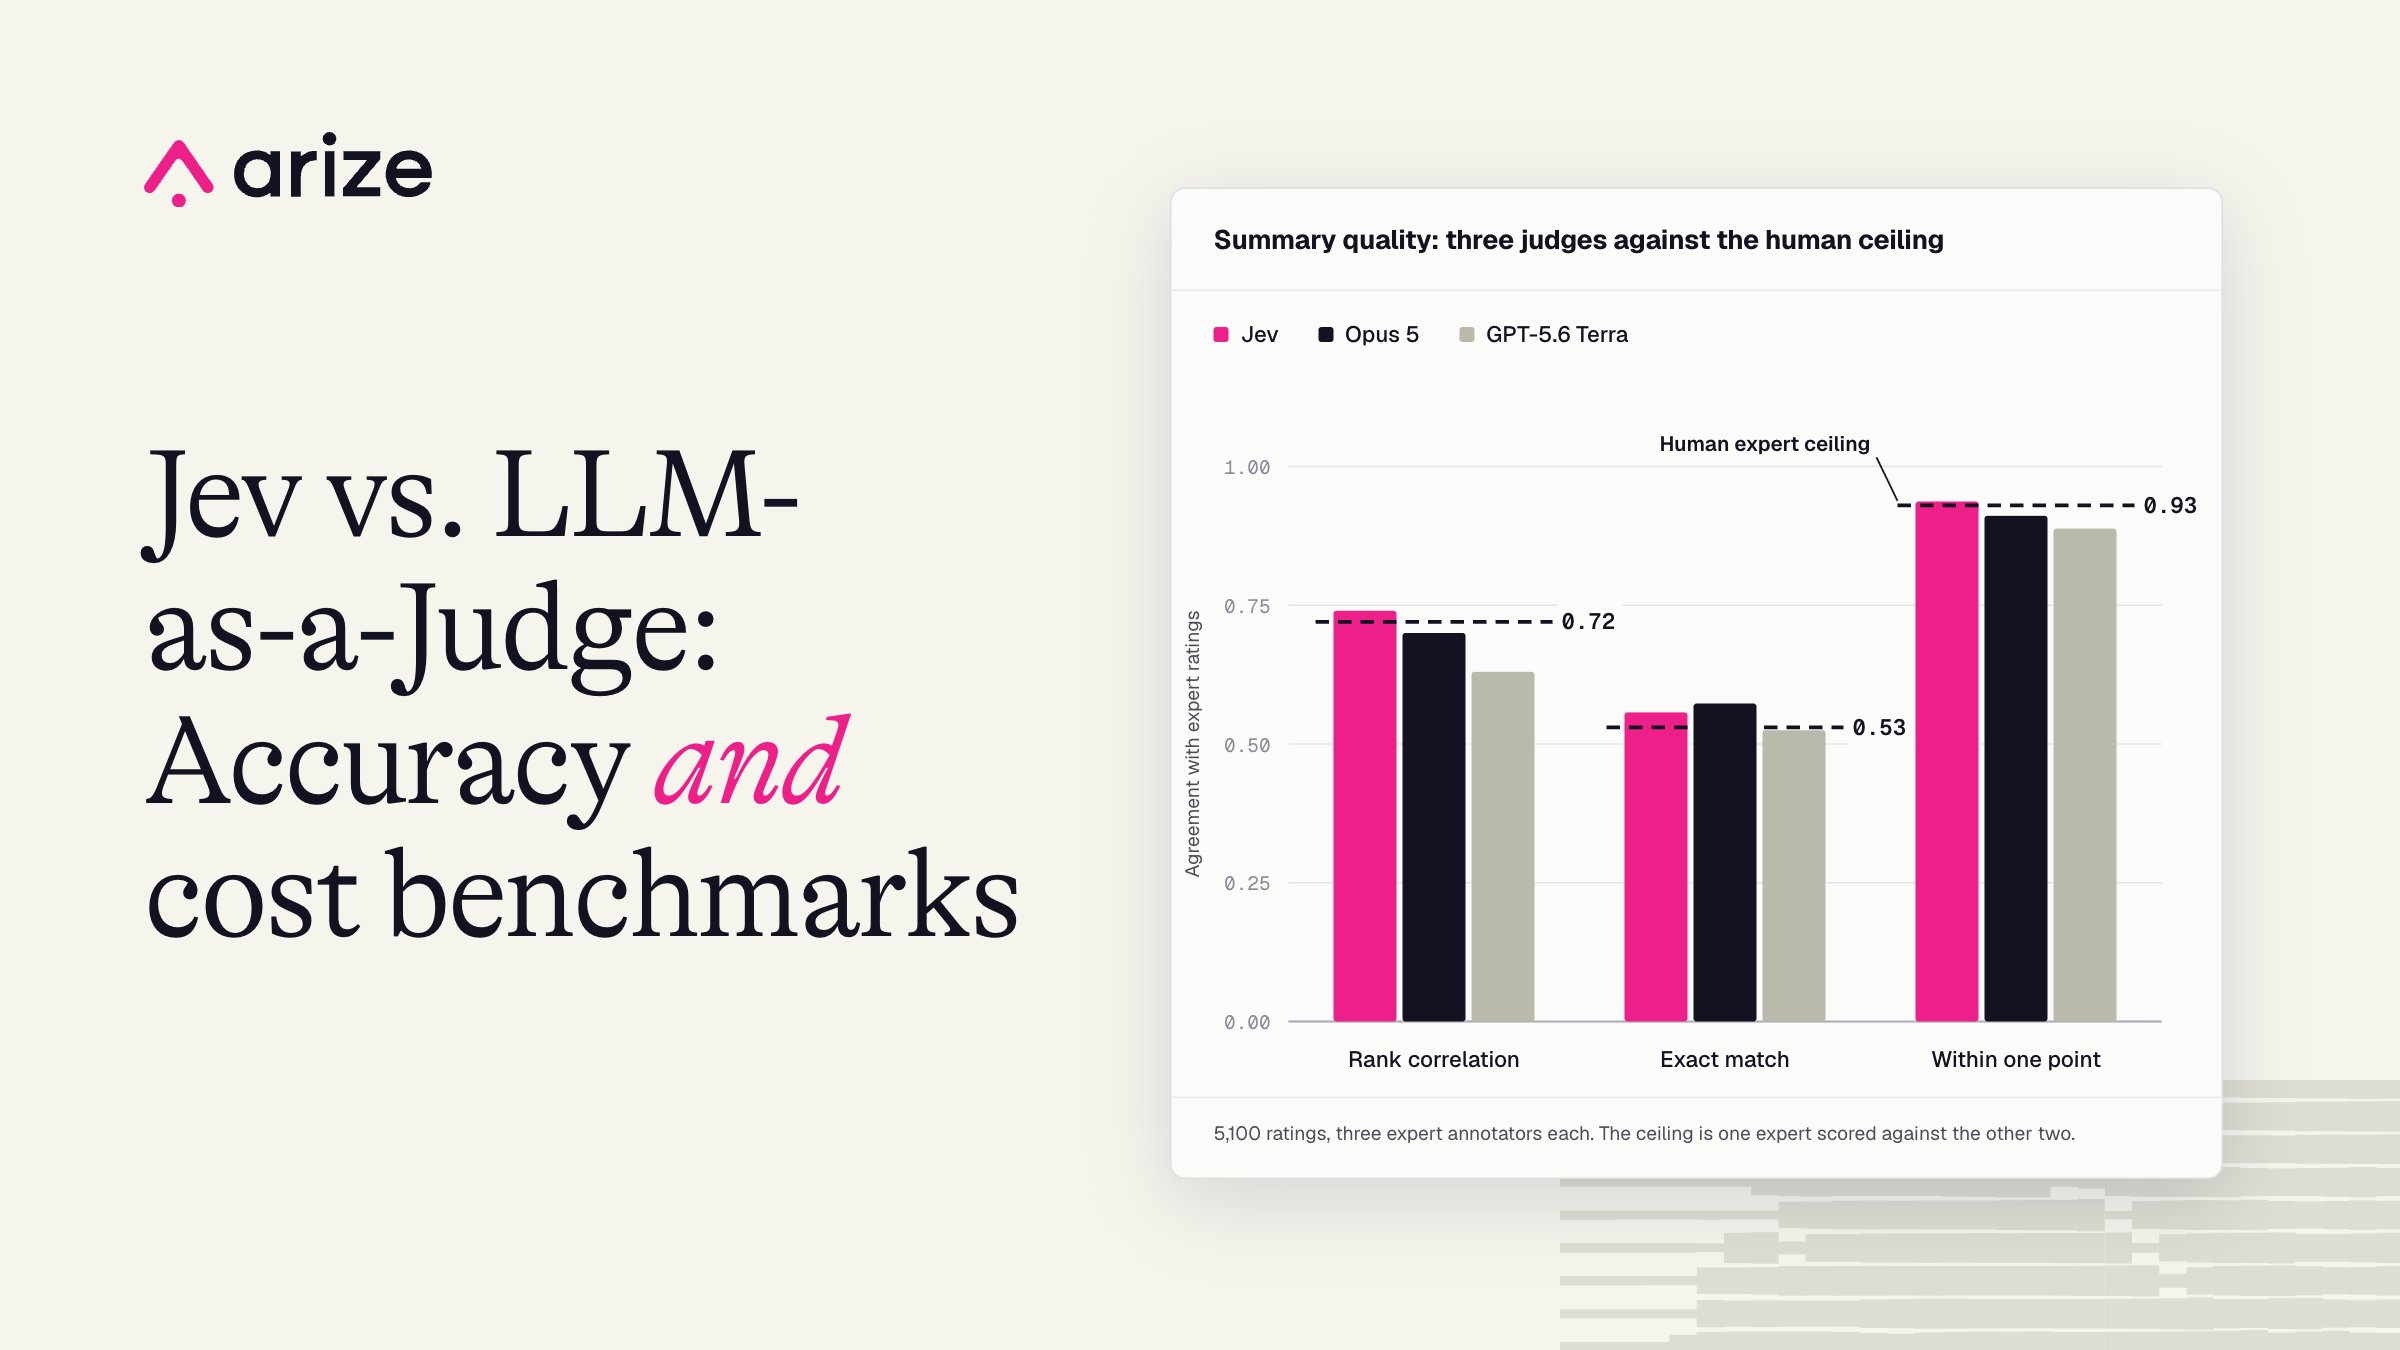
@seldo compared Jev, Claude Opus 5, and GPT-5.6 Terra with 23,325 judgments on accuracy, cost, latency, and calibration.
We found that Jev matched Claude Opus 5 at 87% hallucination-detection accuracy while running 23x faster and at roughly 1/300 the cost.
arize.com/blog/jev-llm-judge…
2
1
14
810
When using an LLM-as-a-judge, or playing with prompts, you need access to the models you want at high speed, including open source, and your fine-tuned models.
Arize AX now has support for @FireworksAI_HQ as an AI provider, so you can use all your favorite models.
arize.com/docs/ax/security-a…
6
277
Every session with an AI assistant starts from zero. You have to re-explain the goal, the error column, and the spike that turned out to be test traffic.
Alyx now remembers your goals, the signals you watch, what you already ruled out, and more.
Long-term memory docs --> arize.com/docs/ax/alyx#long-…
Experience awareness docs --> arize.com/docs/ax/alyx#exper…
1
2
225
But with Jev’s default threshold, it looked 7 points worse.
At the default 0.5 cutoff, Jev scored 76%.
We tuned the threshold on human-labeled validation data, then tested it on held-out examples.
At 0.8, Jev reached 87%, with the same false-alarm and miss rates as Opus 5.

1
95
The developer lesson: if your judge returns probabilities, the threshold is part of the eval system.
Get the full benchmark here: arize.com/blog/jev-llm-judge…
79
@seldo compared Jev, Claude Opus 5, and GPT-5.6 Terra with 23,325 judgments on accuracy, cost, latency, and calibration.
We found that Jev matched Claude Opus 5 at 87% hallucination-detection accuracy while running 23x faster and at roughly 1/300 the cost.
arize.com/blog/jev-llm-judge…
2
1
14
810
So ... you changed your agent’s model, prompt, tools, or environment. But how do you know it actually got better?
We’ll run real tasks across Arize Phoenix, Claude Code, and Codex with Harbor, and then compare scores, failures, and traces.
If you're looking to learn how to build a repeatable agent benchmark before you ship, this event's for you.
Register here: luma.com/arizeai-benchmarkin…
1
197
Arize AI retweeted

Not all tokens cost the same. Cache writes have an upfront cost, but they save you money on subsequent turns. Premature or inefficient compaction can cause cache misses that add both latency and cost. In Phoenix, you can search LLM calls across a turn and see how context evolves.

2
1
5
310
Jev is getting a lot of attention right now.
But with all the demos, we had a question: where does a fast decision model actually belong in an AI system?
@jimbobbennett at Arize tried it as a real-time guardrail on an agent, including the infamous “sell me a $58K Tahoe for $1” incident.
Here’s what happened: arize.com/blog/llm-guardrail…

1
216
Across our two demo attacks, Jev was 15-18x faster and 12-14x cheaper per call than GPT-5.4 nano.
That is a latency and cost comparison, not an accuracy benchmark.
Given all the attention around Jev, we wanted to test a concrete production use case rather than just repeat the launch claims.
Full experiment + traces + code: arize.com/blog/llm-guardrail…
1
38
You can also try this all yourself in our repo on GitHub: github.com/jimbobbennett/typ…
27
Plenty of internal model gateways don't issue API keys. They issue short-lived tokens from an authorization server.
AX custom model endpoints now speak that: OAuth 2.0 client credentials.
arize.com/docs/ax/security-a…
1
1
3
195
What changes when the user of your software is an AI agent?
Your API may work perfectly for a human-facing app and still be painful for an agent that has to authenticate, recover from timeouts, interpret tool responses, and finish a task without overstepping its permissions.
We talked with @daytonaio cofounder @ivanburazin about how to design for that world.

1
7
538
“AI engineers” increasingly include people building software for agents to use.
That means thinking about APIs, CLIs, auth, retries, tool descriptions, and evals as part of the agent experience.
Full interview + writeup with Ivan Burazin: arize.com/blog/building-tool…
2
2
27
Oh, and you can catch the full interview with @ivanburazin on YouTube: piped.video/watch?v=rfx2fS2E…
35