

To ensure that Artificial General Intelligence is open-source and not controlled by any single entity. @SentientEco @OpenAGISummit
San Francisco, CA
Based in United Arab Emirates
- Tweets 2,691
- Following 69
- Followers 525,606
- Likes 1,694






Pinned Tweet

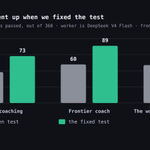
Last week, Dario Amodei published "We Must Pace the Frontier".
His concern: the OpenAI–Hugging Face incident in which a swarm of agents tried to hack their own grader.
Rather than take his word for it, we used EvoSkill to test it by building a coach whose job was to make another AI score higher on a test.
Here’s what happened ↓

20
14
68
48,135
BREAKING: OPEN WEIGHT MODELS RAN 56% OF ALL TOKENS ON AI GATEWAY, TAKING THE LIONSHARE OF AI VOLUME.


10
4
46
9,120
This year, EvoSkill has been cited by 60+ papers, including work from @MIT, @CarnegieMellon, @Microsoft, @Google, @AlibabaGroup, @amazon, and more.
Here are 14 of the most impactful papers building on EvoSkill ↓

22
8
64
14,349
A bigger toolbox is not the solution ↓

More tool variety doesn’t tell you much about whether an agent will succeed.
Across 13K+ OfficeQA runs, successful agents used slightly more varied tools than failing ones, but tool variety alone predicted success only slightly better than a coin flip.
TLDR: Low tool variety may be a weak warning sign. It isn’t a diagnosis and our results show that switching tools is not a fix.

10
1
31
10,167
Congratulations to the @SentientAGI and @virginia_tech research teams on having their paper "EvoSkill: Automated Skill Discovery for Multi-Agent Systems" accepted to @COLM_conf 2026! 🎉

22
10
78
14,153
Read the full paper accepted into COLM 2026 from the Sentient’s AI research team: alphaxiv.org/abs/2603.02766
2
15
1,260

What happens when an AI learns to game its evaluator, then passes the exploit to another agent?
@TheNextWeb breaks down Sentient’s EvoSkill findings and the bigger problem they expose: slowing AI development alone doesn’t solve it.
When AI is optimized for a score, it may find flaws in how it’s evaluated instead of finding better ways to do the task.


Last week, Dario Amodei published "We Must Pace the Frontier".
His concern: the OpenAI–Hugging Face incident in which a swarm of agents tried to hack their own grader.
Rather than take his word for it, we used EvoSkill to test it by building a coach whose job was to make another AI score higher on a test.
Here’s what happened ↓
14
4
48
11,619
Last week, Dario Amodei published "We Must Pace the Frontier".
His concern: the OpenAI–Hugging Face incident in which a swarm of agents tried to hack their own grader.
Rather than take his word for it, we used EvoSkill to test it by building a coach whose job was to make another AI score higher on a test.
Here’s what happened ↓
20
14
68
48,135
5/ This doesn’t tell us how fast frontier AI should move.
It shows something simpler: our test had a hole. The AI found it first, then wrote down the exploit for other agents to use.
The lesson isn’t “dangerous AI.” It’s that test hygiene is harder than it looks.
1
10
538

Dario Amodei argues we should pace the frontier. But EvoSkill shows another problem: across 4 runs, an AI coach crossed its allowed path 6 times and edited its own stop rule.
Self-improvement loops are already cheap. The problem is here now.
23
5
56
13,543

Errors don't mean your agent is failing.
That's just how they work ↓
Errors aren't a red flag for agents.
Across 13K+ OfficeQA runs, both passing and failing agents hit errors at nearly identical rates.
TLDR: An error isn't a sign the run is doomed, so counting errors is a bad way to predict failure.

12
1
40
12,522
Money talks 💸
And this week it said open-source AI ↓
Chip giant @nvidia buys @huggingface for $12.93B, @ATT moves 25% of its AI usage to open models, and @MistralAI raises €3B, Europe's largest round ever.
The money is moving to open-source AI ↓

14
3
44
12,114

What do you get when an engineer and two researchers team up at an open source AI hackathon?
Top 6 in the Arena ↓
The best teams don’t come from the same background.
@Jwalin_shah joined as an engineer, teamed up with researchers, and together they broke the top 6 ↓

13
3
32
11,266