

The compute efficient layer for AI inference
- Tweets 240
- Following 30
- Followers 178
- Likes 194
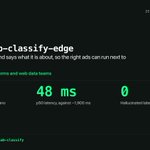


ALT ZeroGPU card for zlm-v1-iab-classify-edge. Reads a web page and says what it is about, so the right ads can run next to it. For publishers, ad platforms and web data teams. Benchmark figures: 66% win rate against gpt-5.4 nano, 48 ms p50 latency, against ~1,900 ms, 0 hallucinated labels, against 1,796.

ALT ZeroGPU card for ZLMs. Small AI models that each do one job well, instead of one big model doing everything. For any team running AI at scale. Benchmark figures: 5 zlms in the catalog today, 50+ languages, no translation step, $0.02 per 1m input tokens.

ALT Limelight case study card: 2.88 million prospect rows enriched on ZeroGPU in six weeks, 9.2x lower cost than Claude Haiku and 3.2x lower than Gemini 3.5 Flash-Lite, $12,739 saved.


