

Caleb Writes Code (YouTube 110k) // Google Developer Expert (AI & Cloud) I chronically over-analyze everything.
USA
- Tweets 461
- Following 188
- Followers 2,149
- Likes 213


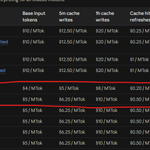


Opus 5.5 and GPT-6 Sol/Luna across the cost and token efficiency as we continue to see intelligence scale

19
514
Something I noticed recently is my writing style is starting to mimic AI, and I'm sure my reasoning is influenced heavily by how LLMs help me think through things.
14
319
Both Anthropic and OpenAI are cutting API prices by making inference cheaper.
Anthropic cuts pricing 20%-60% on Opus 5.5 and OpenAI cuts 50% on their GPT-6 Sol/Luna.
While Opus 5.5 still incredibly token inefficient, cost of intelligence is a different story unfolding.

14
305
Anthropic dropped the token cost by 20% across the board and 60% on cache hit and refreshes on Opus 5.5 compared to Opus 5.
It also spends 65% more tokens than Opus 5. Certainly an improvement but definitely skeptical..

2
21
612


this is making me want to play sc1 again

Last week I launched Brood War Bench.
TLDR;
- Agents have a long way to go before they can annihilate the Terrans
- Codex plays cheese and confuses the opponents
- @Grok is still too dumb to play
🧵
[Below Clip is Opus killing Fable who spent too much on tech]

1
457
"Built in public" is such a huge flex that not many labs can actually claim.

Introducing Xiaomi MiMo-V2.6 — Pro & Flash.
Frontier intelligence, all the modalities, built in public.
🔹 Two omnimodal models, advancing through scaled reinforcement learning
🔹 Pro performs on par with Claude Opus 5 and GPT-5.6 Sol across most agent benchmarks
🔹 Pro scores 46 on the Artificial Analysis Intelligence Index — the highest among open-source models
🔹 Stronger coding, computer use, 3D reasoning and creative capabilities
🔹 Open model weights, technical report, RL environments and training code
Blog:mimo.xiaomi.com/mimo-v2-6

1
56
2,073
Everybody wants to talk about cost efficiency with Jev but Jev is extremely token inefficient.
4
12
1,821
I'm more surprised by what Jev stands for than what the model is capable of.
2022 was a critical moment in AI when we switched from token prediction as the post training objective to instruction following.
But by virtue or picking RLHF as the one to scale, we lost out big time on what else language models could be capable of.
And TypeSafe AI is claiming RLCD (Calibrated Decision) as an alternate path that could genuinely chart a different path than the orthodox method that we've known to scale all along.
Incredible.
4
3
109
7,989

DeepSeek-V4.1-Flash is beautifully crafted model that introduced so many bold takes on model architecture.
With CED, the model only activates 50% of the model during prefill which saves huge compute overhead, and CSA2 on top allows KV Cache reduction without sacrificing quality.
mHC optimization they added in kernels by simply rearranging the algebra on the residual operation also helps save communication overhead between SM and HBM.
Every inch of the model was built with intention and I can see it reading through the entire research paper.
Great work @deepseek_ai team in constructing this, but more importantly, sharing the knowledge to the world. This is invaluable.

2
1
18
643
For detailed step by step breakdown:
calebwritescode.substack.com…
1
135
My first Substack post covering DeepSeek-V4.1-Flash!
I go through DeepSeek's new CED, Mega-mHC, kernel optimization, Engram, and more.
calebwritescode.substack.com…
5
389
DeepSeek V4.1 Flash paper is a rabbit hole... don't let the ".1" increment fool you. it's almost an entirely new model.
6
363
hey, @deepseek_ai
saying that CSA2 exploits all three (entry size, seq dim, and layer dim) doesn't seem fair.. sequence and layer dimension makes sense to me.
but doesn't CSA2 just leverage existing MLA for entry size optimization?

1
177
DeepSeek found a way to maintain decode at near constant where going from 4k to 1M context only increases FLOP by 25%.
Just goes to show you how China is getting around the compute bottleneck with insane precision work here.

2
256
In less than 3 years, DeepSeek reduced KV footprint in HBM by 432X, currently at 890 bytes per token. This absolutely blows my mind.
That's (for 1M context) 389GB to < 1GB compression in just 3 years time directly challenging the Jevon's paradox in the memory sector.
DeepSeek is pushing many pareto forward without sacrificing capability. Incredible..


1
4
24
993